
Overview
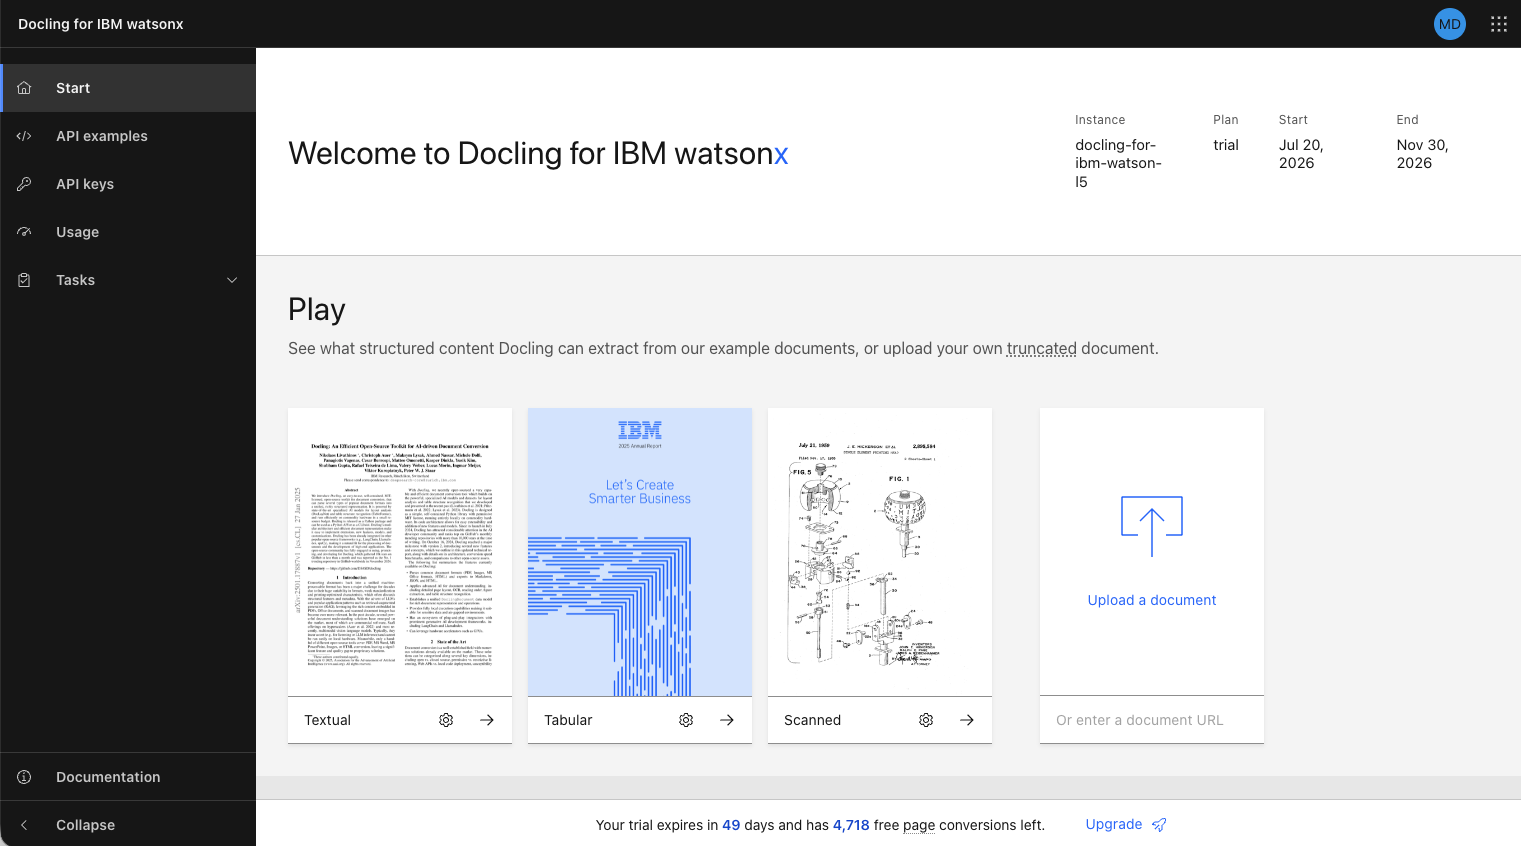
Turn documents into AI-ready data with Docling for IBM watsonx
Enterprise knowledge is locked in PDFs, scans, slide decks and spreadsheets that AI can't use reliably. Docling for IBM watsonx turns them into clean, structured, AI-ready data: Markdown for prompts, chunks for retrieval, and DocLang for the full structure. It runs as a managed service, so there are no models or GPUs to operate.
Quick Start
Convert your first document in five minutes.
Concepts
Outputs, DocLang, chunks and how requests work.
Key features
Single and batch conversion
One document with low latency, or whole collections in one request.
Connectors
S3, Azure Blob, Google Cloud Storage, Google Drive, SharePoint, Box, FileNet and Databricks.
RAG-ready chunks
Structure-aware chunks, streamed to Kafka or indexed into OpenSearch and AstraDB.
Many input formats
PDF, Word, PowerPoint, Excel, HTML, images, EPUB, email and more.
DocLang and more
Markdown, HTML, text, JSON and DocLang, the open format for structured documents.
Structure preserved
Layout, tables, reading order, heading hierarchy and page positions.
What you can build
Streaming document pipelines
Stream document chunks through Confluent Cloud and enrich them with Flink.
AI assistants that read documents
Give IBM Bob or any agent document understanding.
Vector database ingestion
One API call from a document library into AstraDB.
Bulk document migration
Convert whole buckets and folders into AI-ready formats.
Docling and Docling for IBM watsonx
Docling is an open-source document intelligence toolkit, created by IBM Research and hosted by the LF AI & Data Foundation. Docling for IBM watsonx delivers the same technology as a managed service:
| Open-source Docling | Docling for IBM watsonx | |
|---|---|---|
| Runs on | Your machines, with models and optionally GPUs | IBM Cloud, fully managed |
| Best for | Local development and experimentation | Production workloads |
| Updates | You upgrade packages and models | Automatic, always the latest models |
| Scale | Limited by your hardware | Batch conversion of whole collections |
| Integrations | Python library and CLI | REST API, Python and Java SDKs, CLI, connectors, MCP and agent skills |
Both preserve what generic text extraction loses: layout, tables, reading order and the relationships between elements. That gives retrieval and downstream AI more trustworthy input, at a fraction of the cost of sending every page to a frontier model.
Getting started
- Sign up at ibm.com/products/docling. A free trial is available.
- Follow the Quick Start to convert your first document in a few minutes.
- Browse the tutorials and the examples repository for end-to-end builds.